Coffee Sales Data Analysis Using AWS
Business Scenario
The goal of this project is to design an AWS-based analytics solution to process and analyze the Coffee Bean Sales Raw Dataset from Kaggle. This solution will provide actionable insights into sales performance, customer behavior, and product profitability by leveraging Amazon S3, AWS Glue, and Amazon Athena.
The dataset contains coffee sales transactions with the following key tables:
- Customers – customer details such as name, location, and contact information.
- Products – coffee product details including type, roast, and pricing.
- Orders – transactional sales records including quantity, profit, and date.
Techniques
The project leverages Amazon Web Services (AWS) for its data pipeline. The core services utilized are:
- Amazon S3 (Simple Storage Service): Used for storing and retrieving any amount of data.
- AWS Glue: Employed as a fully managed ETL (Extract, Transform, Load) service for data processing.
- Amazon Athena: Used as an interactive query service to analyze the transformed data.
Workflow
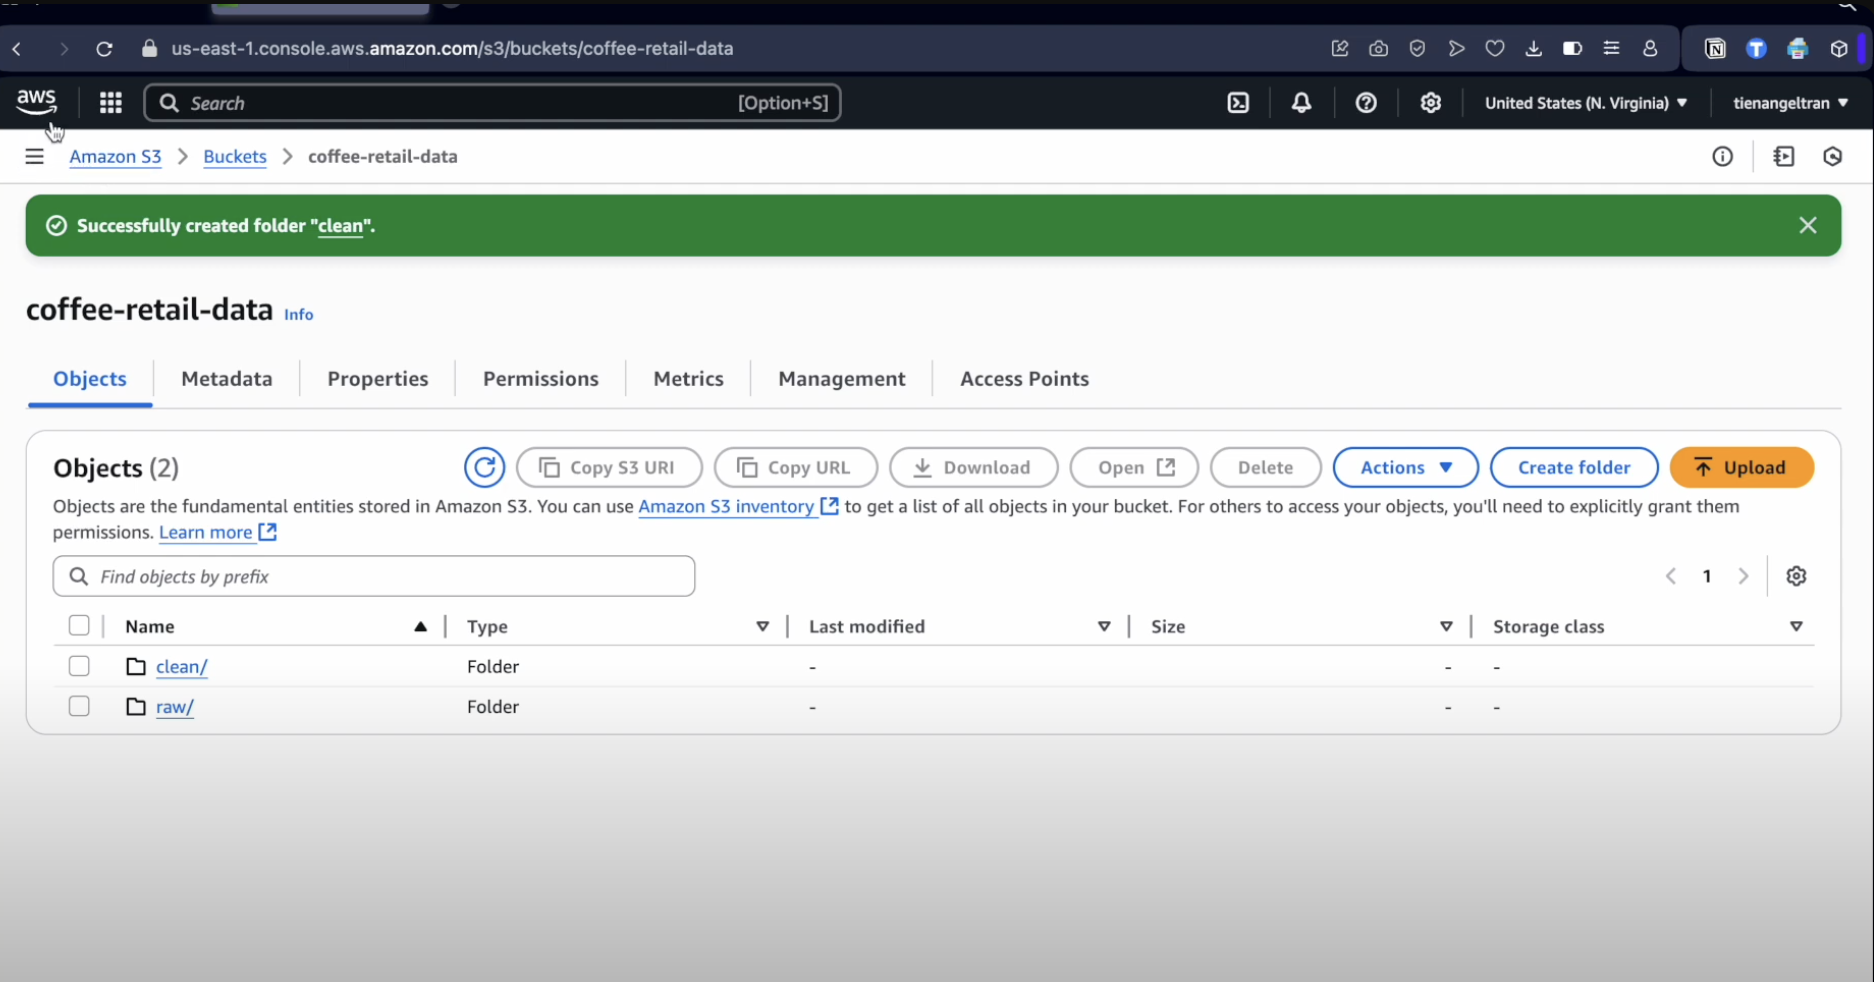
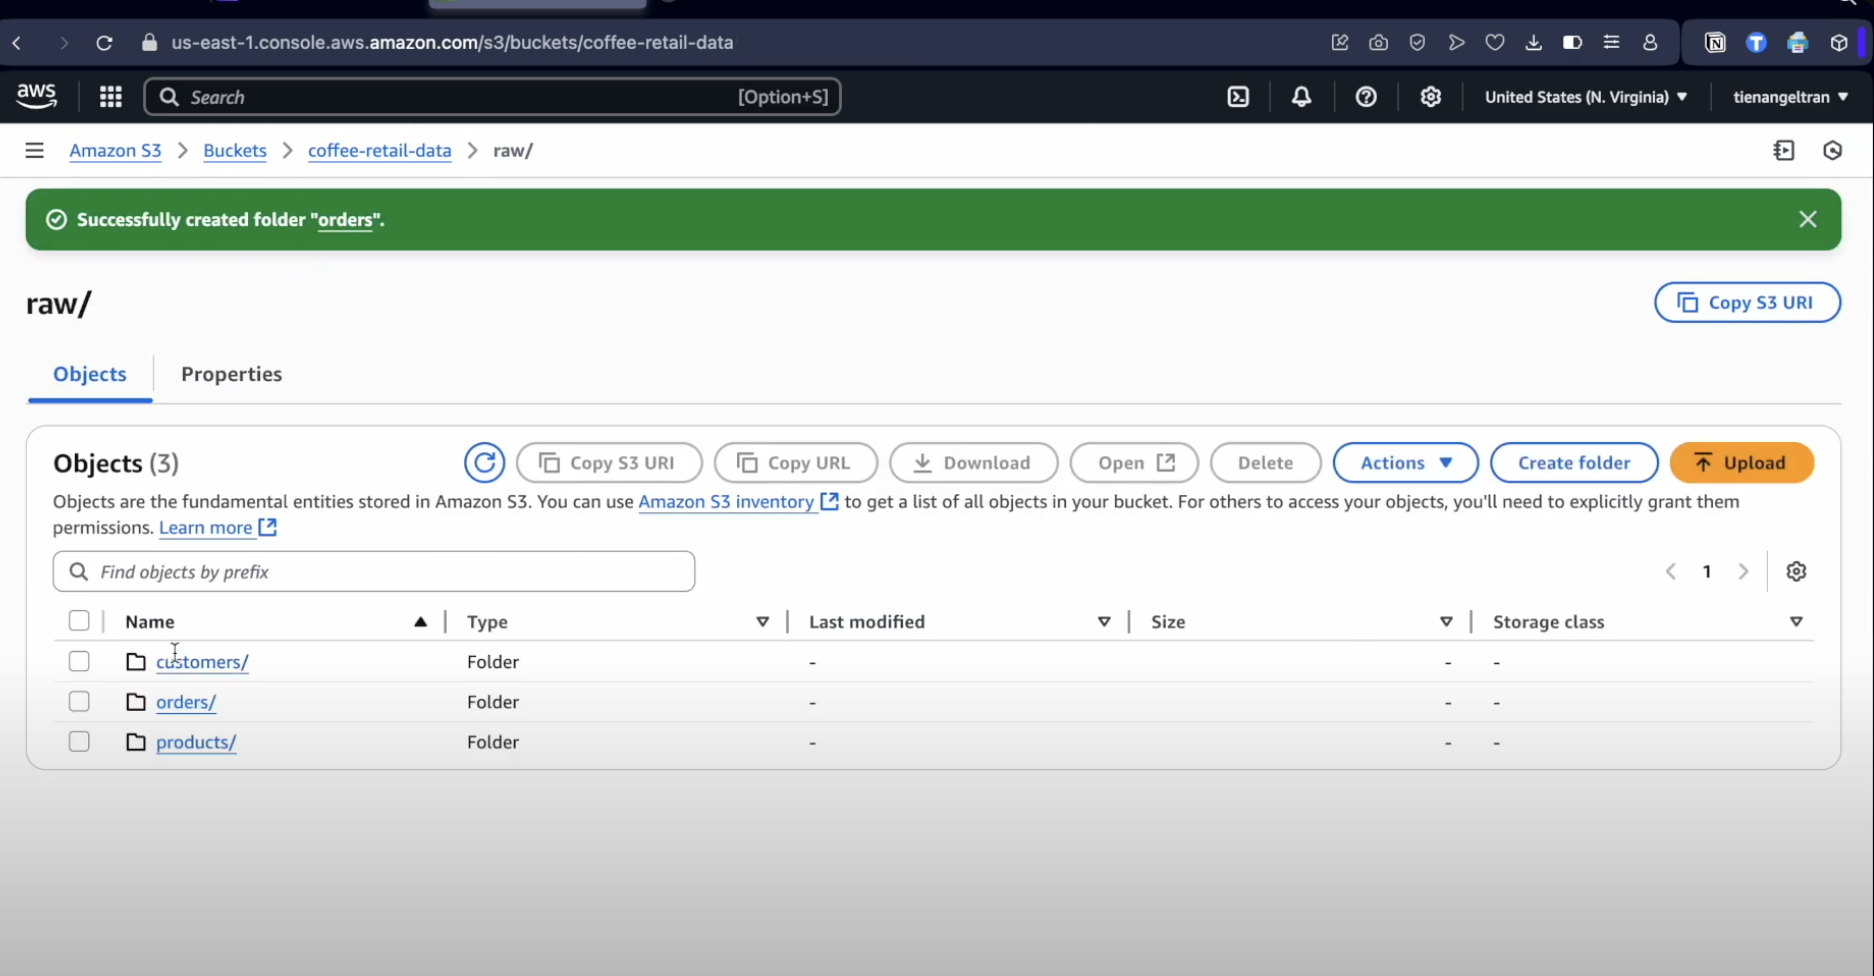
Step 1: Upload CSV Files to S3. This is the initial step where the raw coffee sales data, including customer, product, and order information, is stored in S3 buckets2.
Step 2: Catalog the Data. This involves creating SQL-style table catalogs for the raw datasets2, specifically for the table_customers, table_products, and table_orders tables. This makes the data discoverable and queryable.
Step 3: Clean & Join Data with AWS Glue ETL Job. This crucial step involves:
- Adding the three raw data sources (Customers, Products, Orders)
- Performing inner joins to combine these datasets: first, Customers with Orders using ‘Customer ID’ as the key, then the resulting dataset with Products using
Product IDas the key. - Applying a transformation to change the schema and drop duplicate customer_id and product_id columns after the joins.
- Defining the output target as Amazon S3, with the data saved in CSV format without compression to a specified clean data path (
s3://coffee-retail-data/clean/). - The final combined schema for the
coffee_salestable includes product, customer, and order details.
Step 4: Query Transformed Data with Athena. After the data is cleaned and joined by AWS Glue, it is ready for analysis.
Functionalities
- S3 bucket folders
- Visualize ETL
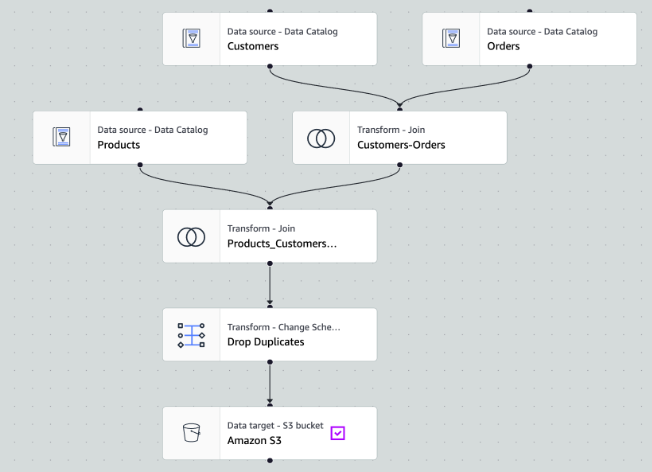
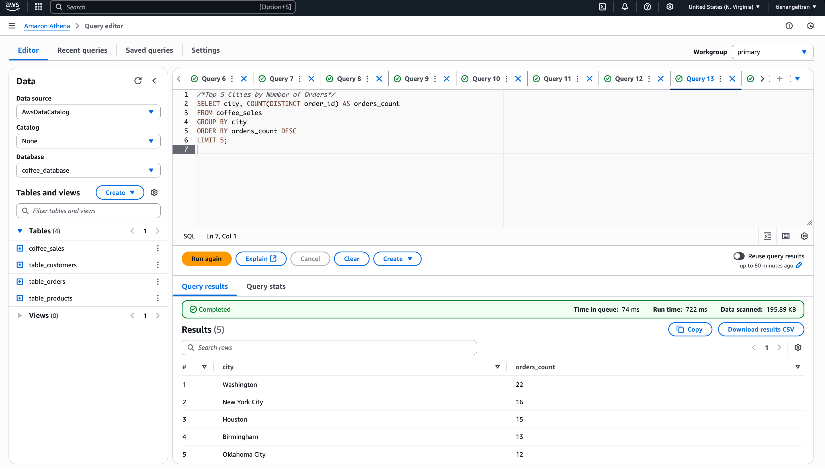
The transformed data stored in S3 can be interactively queried using Amazon Athena to derive various business insights. Examples of functionalities include:
• Identifying the Top 5 Cities by Number of Orders.
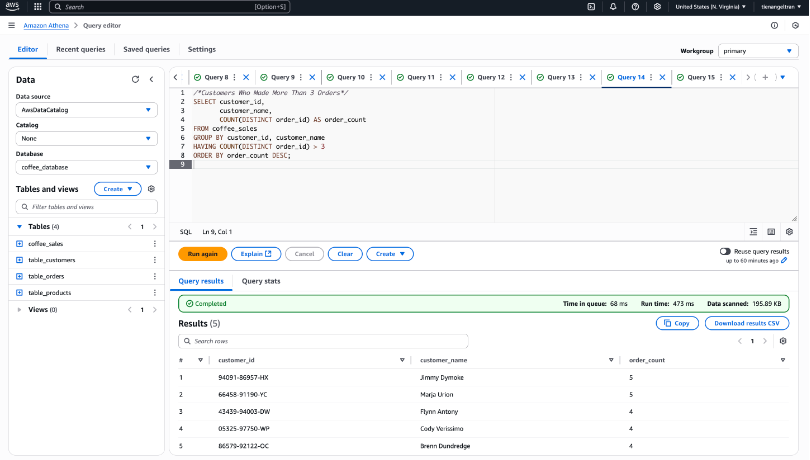
• Listing Customers Who Made More Than 3 Orders.
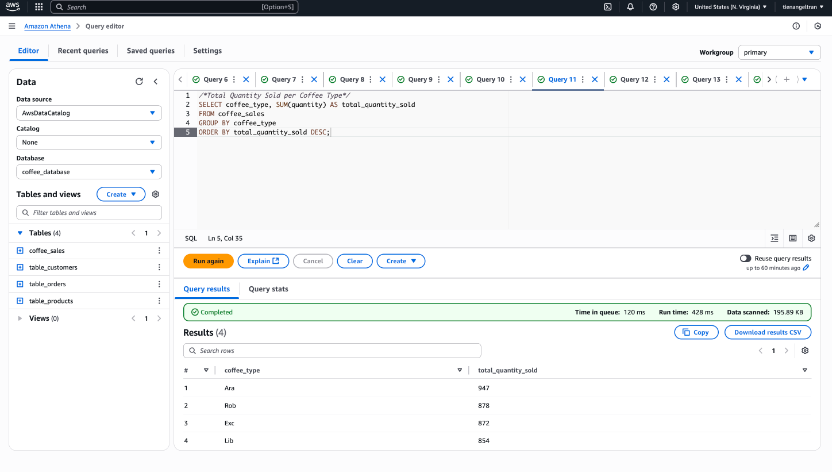
• Calculating the Total Quantity Sold per Coffee Type.
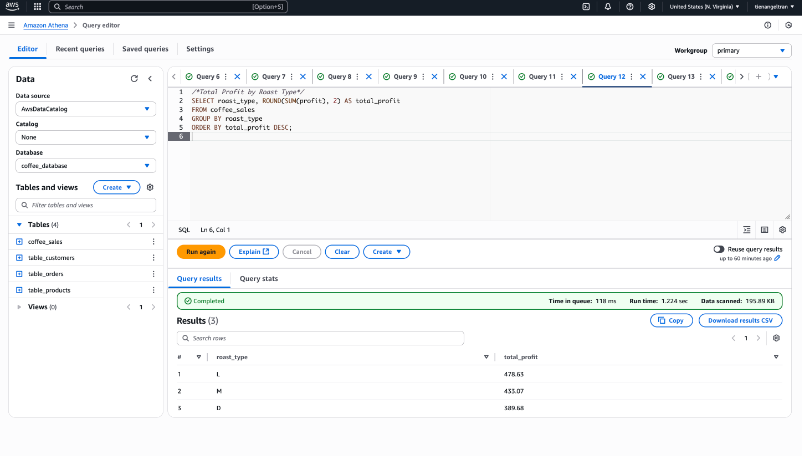
• Determining the Total Profit by Roast Type
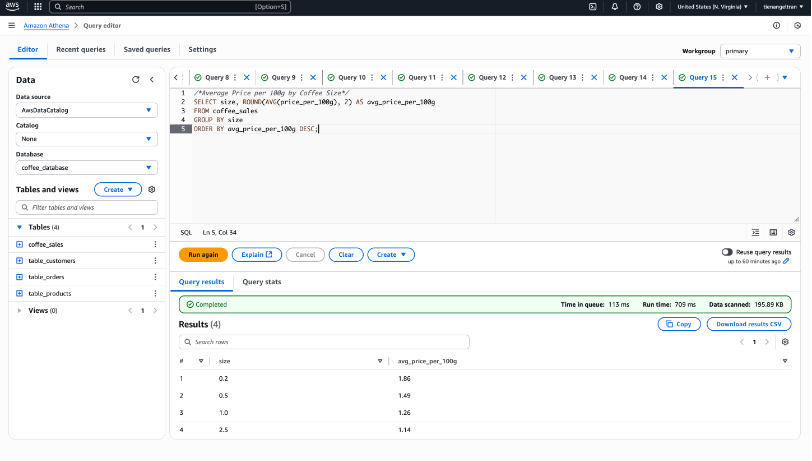
- Average Price per 100g by Coffee Size